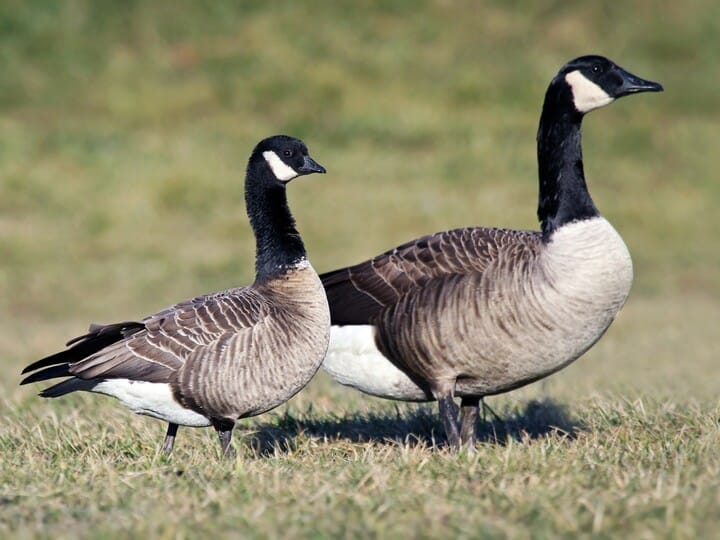
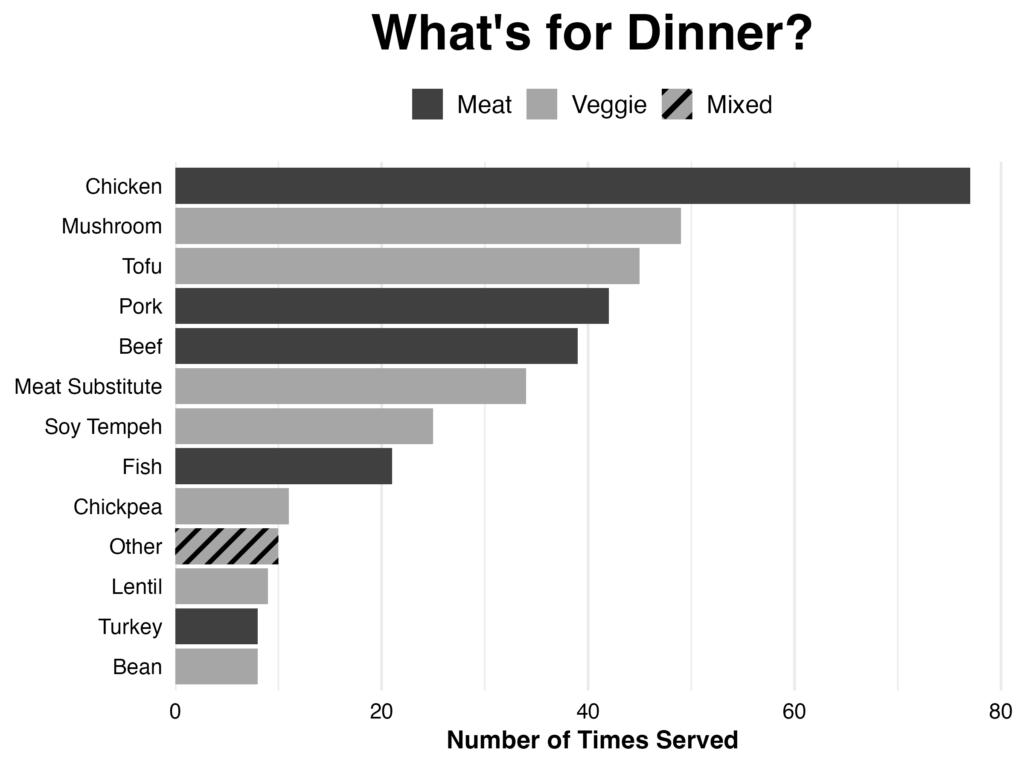The Cackling Goose and the Canada Goose: can you tell them apart if they aren’t right next to each other? People at Oaks Bottom probably can’t.
Image from Ryan Schain via Cornell’s allaboutbirds.org
This week we looked at the geese present on and around Reed’s campus. Anecdotally, I think there are more geese on campus than there were when I was here in the mid to late 2000s. If we want to look at confirming or denying that assertion there are a number of routes that we could take. I’m going to go through one that I think might be people’s first thought for addressing this question and point out some potential pitfalls in what might seem like an otherwise straightforward analysis.
Some of the problems discussed here will be specific to the topic, but many can be broadly applied to other types of research. When you’re working on a project, it’s always good to check your assumptions to make sure you thoroughly understand what’s in your data, including how it is collected, potential confounding variables, and issues with masking or silent imputation (for example, how null data is handled).
Public Data & Citizen Science
Public, online repositories of data are extremely useful for all kinds of research. OpenStreetMaps has an extensive database for maps and location labeling of all kinds (as described a little in the previous blog entry). PurpleAir and OpenAQ have data on air quality that is fine-scaled and up to the minute because of user-submitted measurements. Globe at Night is a citizen science initiative to measure light pollution around the world and relies totally on individual contributions. These types of organizations provide a wealth of useful knowledge that is available for anyone to use, but you have to be careful how you interpret it.
This project relied on eBird data. eBird is a site for birders to submit lists of birds that they saw or heard, how many there were, where they were, and a number of other things. Birders are often obsessive nutjobs1, so that makes eBird one of, if not the, the largest repository of biodiversity data in existence. Scientists use it to track migration, population trends, and the effects of climate change and habitat loss, and anyone can explore the maps and species data online. You can look at birding hotspots worldwide or right in your neighborhood, like the one at Reed Lake (aka, the canyon).
eBird is a bit cumbersome to use, so I accessed its data via the Global Biodiversity Information Facility, which pulls data from a number of open access sources (it’s very cool, check it out). To do this I used an R package called {rgbif} to pull data from three eBird hotspots near Reed (Reed Lake, Oaks Bottom, and the Rhodie Gardens) for both Cackling Geese (Branta hutchinsii) and Canada Geese (Branta canadensis). That code is in the ‘pull_geese.R’ script on the GitHub, but the gist of it relies on having a free user key for eBird and this function:
This pulls data since 2010 for the three locations (as identified by unique eBird IDs), and that data comes as individual people’s checklists, so a single row, looks something like this and includes the specific date, whose list it is, and how many birds they saw.
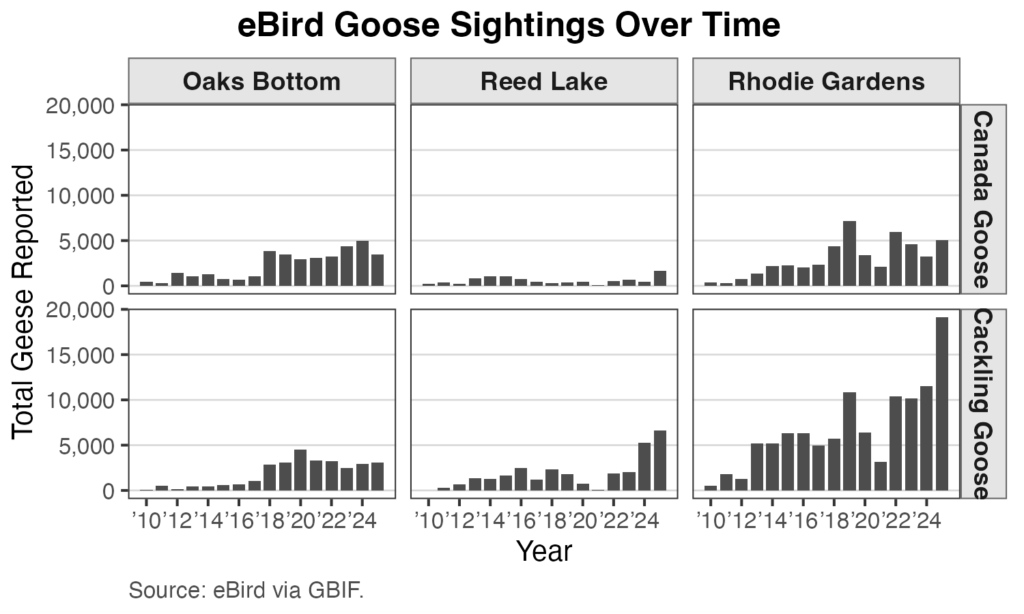
By summing up that data by year, you can get the following figure, which is similar to what is in The Quest, but I added the Rhodie Gardens just for fun.
On the face of it, this is a simple and straightforward way to look at the number of geese over time. But there are a number of issues, some obvious and some not so obvious, that make this graph not as useful as one might initially think.
Problems
The easiest data to use for analysis is highly structured data. This is data that has a design implemented before collection, has a fixed scheme for how it is recorded, and has neat rows and columns. eBird data may appear this way at first but it is actually semi-structured data. The form for entering the bird count data might be the same for everyone, but participants get to choose where, when, and for how long they want to record. They can log every bird they see or just the ones they’re interested in. And their observations are based solely on their own expertise.
Structured vs Semi-Structured Data
An example of similar data that is structured is the USGS North American Breeding Bird Survey. Data is still collected by volunteers, but those volunteers have to officially register with their local government and follow a strict protocol. The routes are random, the survey takes place at the same time each year, participants count for a set length of time, and the skill levels are roughly equally advanced. Because of this every count represents a standardized effort, so year-to-year differences reflect real changes in bird populations rather than differences in how the data was collected.
Let’s dig into the issues.
Sampling Bias
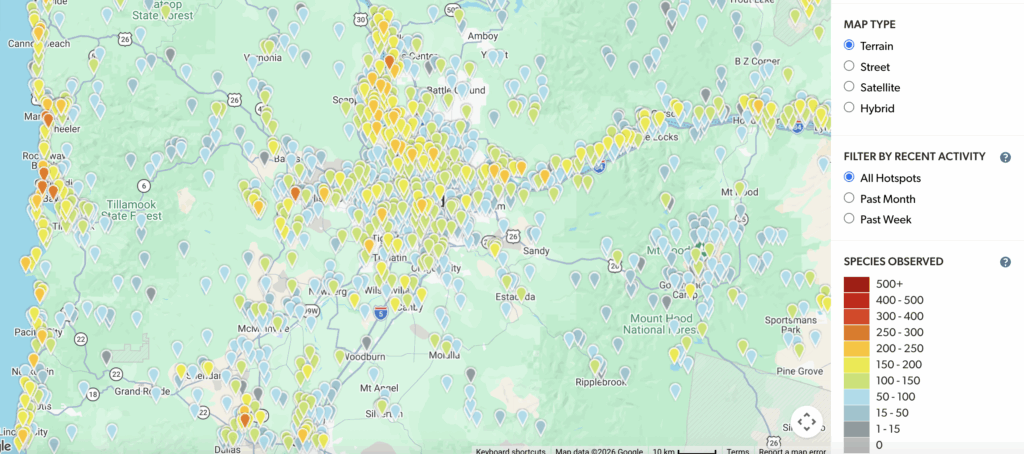
Sampling bias occurs when a sample or survey is not representative of the whole population. As you might expect, people are going to bird in nice, easy to reach places rather than rural, inhospitable, or just plain ugly locations. So eBird checklists cluster near roads, cities, parks, and hotspots, and around wealthy regions where birds are abundant. Just looking at a map of where records are, you can see obvious oversampling in some areas and no data for others. Here’s a map of an area around Portland.
An absence of records in a location obviously doesn’t mean there are no birds there. We expect to see higher numbers of birds recorded in heavily trafficked areas. So, for our goose data, do we really think that geese flock to the Rhodie Gardens far more than to Reed? Perhaps, but think about how likely the average person on Reed campus is to be recording bird totals versus the average visitor to the Rhodie Gardens.
This week, The DataLab made a map of “amenities” that are near Reed. The data comes from OpenStreetMap (OSM), which has a huge amount of useful and free data, but also some very interesting classifications for things! Read on to find out more about why that is and how we made the map.
OSM is a free, editable map of the world built by volunteers. It’s basically Wikipedia for maps. All of its data comes from user-contributed tags, so anyone can add and label features. These are often things like classifying things as residential or commercial with a tag like “landuse=residential” or describing natural features like “waterway=river”.
But people can tag whatever they like, and a lot of fun things are tagged under “amenity”. There are many practical things like fire stations, but there are also tags for things like “icecream” and, my favorite, “dog_toilet”. Sadly, most of the dog toilets are in Europe and there are no tagged locations of dog toilets near Portland, but because anyone can add tags, you could change that!
This is actually my own dog, Charlie, pooping in a weird spot.
Where do you find the data?
All of the data comes from OpenStreetMap and was accessed directly in the R script.
For the print map, I pulled the data live from the Overpass API, which is a free service for querying OSM. The {osmdata} package lets you draw a “bounding box” (just the latitude and longitude boundaries for your map) and then you can query for every feature with a certain tag inside that box. That worked fine for the small area around Reed, but Overpass was unreliable for anything larger than the small box.
# Bounding box vaguely around inner Portland to I-205 on the east
bb <- c(-122.72, 45.46, -122.55, 45.56)
For the interactive map, I wanted the user to be able to zoom out a bit and look at areas around broader Portland, and Overpass kept giving me 502 and 504 errors. This means the public servers were overloaded and big requests were failing. So instead, I downloaded a whole OSM extract of the Portland metro area from BBBike using the {osmextract} package. That file is large, so it isn’t included in the Github repo for this project, but a cached rds file is, so if you’re looking only for the same things I wanted, the repo works well. If you want to expand beyond the amenities I chose to look at, you’ll need to extract the larger file yourself.
# my local file
extract_file <- "/Users/griffinj/Documents/GIS_files/osm_extracts/bbbike_Portland.osm.pbf"

# the cache it creates
cache_file <- "amenities/data/amenities_raw_inner_pdx.rds"
I pulled amenities using the add_osm_feature() function and decided to also add another feature to pull dispensaries, which we’re classified differently as “cannabis shops”. Some of the locations that were pulled were mapped as single points and others were polygons in the shape of the outline of their buildings. I just wanted to plot everything as points, so I converted the polygons to “centroids” (the center point of the polygon) so that everything could be plotted the same way.
# --- Pull amenities from OpenStreetMap -----------------------------------
# Source: OpenStreetMap contributors via the Overpass API (osmdata package).
# Amenities are points, but some are tagged on building footprints, so we
# keep the point and polygon layers and reduce polygons to their centroids.

# Points, plus polygons (buildings) reduced to their centroids.
as_points <- function(osm) {
  polygons <- if (is.null(osm$osm_polygons)) NULL else st_centroid(osm$osm_polygons)
  bind_rows(osm$osm_points, polygons)
}

amenities_osm <- opq(bbox = bb) |>
  add_osm_feature(key = "amenity") |>
  osmdata_sf()

# # Dispensaries are tagged as shops, not amenities, so they need their own query.
dispensaries_osm <- opq(bbox = bb) |>
  add_osm_feature(key = "shop", value = "cannabis") |>
  osmdata_sf()

amenities <- as_points(amenities_osm) |>
  filter(!is.na(amenity)) |>
  transmute(name, amenity)

dispensaries <- as_points(dispensaries_osm) |>
  filter(shop == "cannabis") |>
  transmute(name, amenity = "dispensary")

amenities <- bind_rows(amenities, dispensaries) |>
  st_transform(4326)
How do you make the map?
For the plain print map, I needed a pretty sparse background, so I just added streets from OSM and a shapefile of the outline of Reed.
For the interactive map, I could have a more detailed background and I wanted the user to be able to zoom in and out, so there I used the {leaflet} package to add an ESRI map as the background. {leaflet} is a wonderful package for making interactive maps, so I highly suggest you look into it if you’re going to be working with spatial data. ESRI is an evil overlord that has cornered the market on a lot of GIS software, but they do have a good basic background map. It’s easily added to leaflet plots with just the line addProviderTiles("Esri.WorldGrayCanvas").
The interactive map was actually much easier to make than the smaller black and white map. This is the code that creates the interactive map:
# make the map with leaflet so it's interactive
map <- leaflet(shared, width = "100%") |>
  # provider tiles is what the background of the map is
  addProviderTiles("Esri.WorldGrayCanvas") |>
  # make the Reed boundary distinct
  addPolygons(data = reed, fillColor = "grey50", fillOpacity = 0.35, color = NA) |>
  # add the points
  addCircleMarkers(
    lng = ~lon, lat = ~lat,
    radius = 6, stroke = TRUE, color = "white", weight = 1,
    fillColor = ~pal(type), fillOpacity = 0.9,
    label = ~lapply(paste0(htmlEscape(name), "<br/>", htmlEscape(type)), HTML)
  ) |>
  # center initial map
  setView(lng = reed_center[1], lat = reed_center[2], zoom = 14)
The smaller map took so much more fiddling. By doing these Quest graphics, I’m learning a lot about how hard it is to create useful visualizations when there are a lot of restrictions on style. This map had to be in black and white, so I used shapes to symbolize amenity type, but some places were right next to each other (the places on the corner of Bybee and Milwaukie), so the individual shapes weren’t legible. Making those not overlap was perhaps more trouble than it was worth, but I get stubborn.
To fix the overlap, I grouped any places within 60 meters of each other into a cluster using hclust(). Then I moved each symbol in a cluster onto a small ring around the cluster’s center and drew a thin line back to the true location. That required actually doing some math, so I had to temporarily convert the coordinates to UTM, which is a projection measured in meters instead of degrees. Then I had to actually remember some freaking geometry to get that lines to go to the right places. Here’s the code for the simpler map:
# --- Map -----------------------------------------------------------------
# Keep the most common amenity types and lump the rest into "other".

amenities_plot <- fun_stuff |>
  filter(amenity %in% c("dispensary", "ice_cream", "swingerclub", "pub")) |>
  mutate(type = fct_infreq(amenity))

# Spread out overlapping symbols. Places within `merge_dist` meters of each other
# form a cluster; a cluster's symbols are moved onto a small ring around its center
# and a line points back to each true location.
merge_dist <- 60  # meters
ring_base <- 75   # ring radius = ring_base + ring_step * cluster size, in meters
ring_step <- 15

pts_m <- amenities_plot |> st_transform(26910)  # UTM 10N, meters
xy <- st_coordinates(pts_m)

amenities_plot <- amenities_plot |>
  mutate(
    cluster = cutree(hclust(dist(xy), method = "complete"), h = merge_dist),
    x0 = xy[, 1], y0 = xy[, 2]
  ) |>
  st_drop_geometry() |>
  group_by(cluster) |>
  mutate(
    n = n(),
    angle = 2 * pi * (row_number() - 1) / n,
    radius = if_else(n > 1, ring_base + ring_step * n, 0),
    x1 = mean(x0) + radius * cos(angle),
    y1 = mean(y0) + radius * sin(angle)
  ) |>
  ungroup()

# Back to lon/lat for plotting.
to_lonlat <- function(x, y) {
  st_as_sf(tibble(x, y), coords = c("x", "y"), crs = 26910) |>
    st_transform(4326) |>
    st_coordinates()
}
true_ll <- to_lonlat(amenities_plot$x0, amenities_plot$y0)
shown_ll <- to_lonlat(amenities_plot$x1, amenities_plot$y1)

amenities_plot <- amenities_plot |>
  mutate(
    lon0 = true_ll[, 1], lat0 = true_ll[, 2],
    lon1 = shown_ll[, 1], lat1 = shown_ll[, 2]
  )
moved <- filter(amenities_plot, n > 1)

amenities_map <- ggplot() +
  geom_sf(data = reed, fill = "grey75", color = NA) +
  geom_sf(data = streets, color = "grey80", linewidth = 0.5) +
  geom_segment(data = moved, aes(x = lon0, y = lat0, xend = lon1, yend = lat1), color = "grey30", linewidth = 0.3) +
  geom_point(data = moved, aes(x = lon0, y = lat0), color = "grey30", size = 0.6) +  # true location
  geom_point(data = amenities_plot, aes(x = lon1, y = lat1, shape = type), color = "black", size = 3.5) +
  coord_sf(xlim = bb[c(1, 3)], ylim = bb[c(2, 4)], expand = FALSE) +
  scale_shape_manual(
    name = NULL,
    values = c(dispensary = 16, ice_cream = 17, swingerclub = 18, pub = 15),  # circle, triangle, diamond, square
    labels = c(dispensary = "Dispensary", ice_cream = "Ice cream shop", swingerclub = "Swingers club", pub = "Pub")
  ) +
  theme_void() +
  theme(
    plot.title = element_text(face = "bold", size = 16),
    plot.caption = element_text(color = "grey40"),
    legend.text = element_text(size = 12),
    plot.margin = margin(10, 10, 10, 10)
  )
And that’s for only plotting four amenities! You’ll notice that for doing this map all I needed was good ole ggplot and the geom_sf() command from the package {sf}. That package allows for plotting spatial data within ggplot provided your data objects have either latitude and longitude or a geometry column, if you’re plotting shapes. For a long time, I thought the “sf” in the package stood for “shape files”, but it stands for “simple features”, which actually makes a lot more sense.
Making the tables
I also used another package whose name I thought meant something else in order to make the accompanying summary tables. The tables are easily made with basic dplyr functions, but making them pretty happens with the package {gt}, which stands for “grammar of tables” and not “great tables”, though in this case I think my acronym is superior.
For the simple table in the Quest print, I summarized the number of amenities and their distances and formatted that into a print ready table with {gt}.
# The table covers everything in fun_stuff (the full `fun` list).
fun_sum <- fun_stuff |>
  st_drop_geometry() |>
  group_by(amenity) |>
  summarize(total = n(), avg_dist_miles = mean(dist_miles), sd_dist_miles = sd(dist_miles)) |>
  arrange(desc(total))

# Formatted table, distance as mean ± sd. sd is NA for types with only one place (shows the mean alone).
fun_table <- fun_sum |>
  mutate(amenity = str_to_sentence(str_replace_all(amenity, "_", " "))) |>
  gt() |>
  cols_label(
    amenity = "Type",
    total = "Count",
    avg_dist_miles = "Average Distance (miles)"
  ) |>
  fmt_number(columns = c(avg_dist_miles, sd_dist_miles), decimals = 2) |>
  cols_merge_uncert(col_val = avg_dist_miles, col_uncert = sd_dist_miles) |>  # mean ± sd
  sub_missing(missing_text = "—") |>
  tab_header(
    title = "Fun 'Amenities' Near Reed",
    subtitle = "Distance from the edge of campus"
  ) |>
  tab_source_note("Source: OpenStreetMap contributors") |>
  opt_row_striping() |>
  cols_width(
    amenity ~ px(170),
    total ~ px(110),
    avg_dist_miles ~ px(230)
  ) |>
  cols_align(align = "center", columns = c(total, avg_dist_miles)) |>
  tab_options(data_row.padding = px(10), column_labels.padding = px(10))
For the interactive table, it’s linked to the map using the package {crosstalk}. All you need to do is wrap your dataframe with SharedData$new(), and then any widget built from that shared object responds to the others. So when you pick “ice cream” in the search box, both the map and the table filter at the same time. The table is made with {DT}, which makes sortable, searchable tables. The code here again is a bit easier than the print version, largely because I just accepted the table defaults rather than specifying size and spacing.
# show the name of the thing, the type, distance from Reed, and location
# (just lat and long, address is likely possible, but I got lazy)
table <- datatable(
  shared,
  colnames = c("Name" = "name", "Type" = "type", "Location (lat, lon)" = "location", "Distance from Reed (mi)" = "dist_miles"),
  rownames = FALSE,
  options = list(
    columnDefs = list(list(targets = c(4, 5), visible = FALSE)),
    order = list(list(3, "asc"))
  )
)
Displaying the interactive map
The last step was saving everything as one HTML file. The {htmlwidgets} package and {htmltools} helped here. Normally, you can just save widgets very easily with the function saveWidget(), but because the graphic is technically several widgets stacked together (the search box, the map, and the table), I had to do another little fiddlesome thing. I wrote a tiny throwaway R Markdown file that renders with “self_contained: true“, so everything ends up in one little file. Then I put that file on GitHub Pages in order to have a spot for it to be hosted so I could drop it into this blog.
Unfortunately, WordPress didn’t want to show it. The plan was to have it embedded on this page with an iframe, which is basically a window into another web page. I did some tinkering to make it display at the correct height so that it could talk to the WordPress page and resize itself accordingly. That works on a normal webpage, but WordPress blogs don’t allow iframes from Github! Only from elite sites like TikTok and Instagram [eyeroll emoji]. But here’s the code that would work if WordPress was slightly better.
# --- Layout and save -------------------------------------------------------
# crosstalk package enables bootstrap styling
# needed widget to embed into wordpress as an iframe

# this is supposed to work so the embed can resize itself instead of guessing a
# fixed height and getting an internal scrollbar; to do this the embedding page
# has to "listen" for this - see amenities/README.md.
resize_reporter <- tags$script(HTML("
  (function() {
    function sendHeight() {
      window.parent.postMessage(
        { type: 'amenities-map-resize', height: document.documentElement.scrollHeight },
        '*'
      );
    }
    window.addEventListener('load', sendHeight);
    new ResizeObserver(sendHeight).observe(document.body);
  })();
"))

widget <- tagList(
  bscols(widths = 12, filter_select("type", "Click in box to display specific amenities", shared, ~type, multiple = TRUE)),
  bscols(widths = 12, legend_box),
  bscols(widths = 12, map),
  bscols(widths = 12, table),
  resize_reporter
)

# this is technically a couple widgets because of the tagList, so can't just use
# saveWidget(), so render through a throwaway .Rmd instead -
# rmarkdown shells out to pandoc, so it needs to be installed
Sys.setenv(RSTUDIO_PANDOC = path.expand("~/.local/bin"))

# this just compiles everything as html with a title and whatnot
rmd_path <- tempfile(fileext = ".Rmd")
writeLines(c(
  "---",
  "title: Ice Cream & Grave Yards - 'Amenities' Near Reed",
  "output:",
  "  html_document:",
  "    self_contained: true",
  "---",
  "",
  "```{r echo=FALSE, warning=FALSE, message=FALSE}",
  "widget",
  "```"
), rmd_path)

# save it to a file
rmarkdown::render(
  rmd_path,
  output_file = "amenities_interactive.html",
  output_dir = "amenities",
  envir = environment(),
  quiet = TRUE
)
Want the full code?
We have a Github repo for this project where you can access everything use to create these maps. It contains two scripts: one for building the image printed in the Quest and one for the interactive map below. From those a map and a table image are created for the Quest and an html file is created for the interactive map.
Open Street Maps has a ton of useful data, so I really encourage people to check it out for a wide variety of projects. And if you ever need help, visit the DataLab!
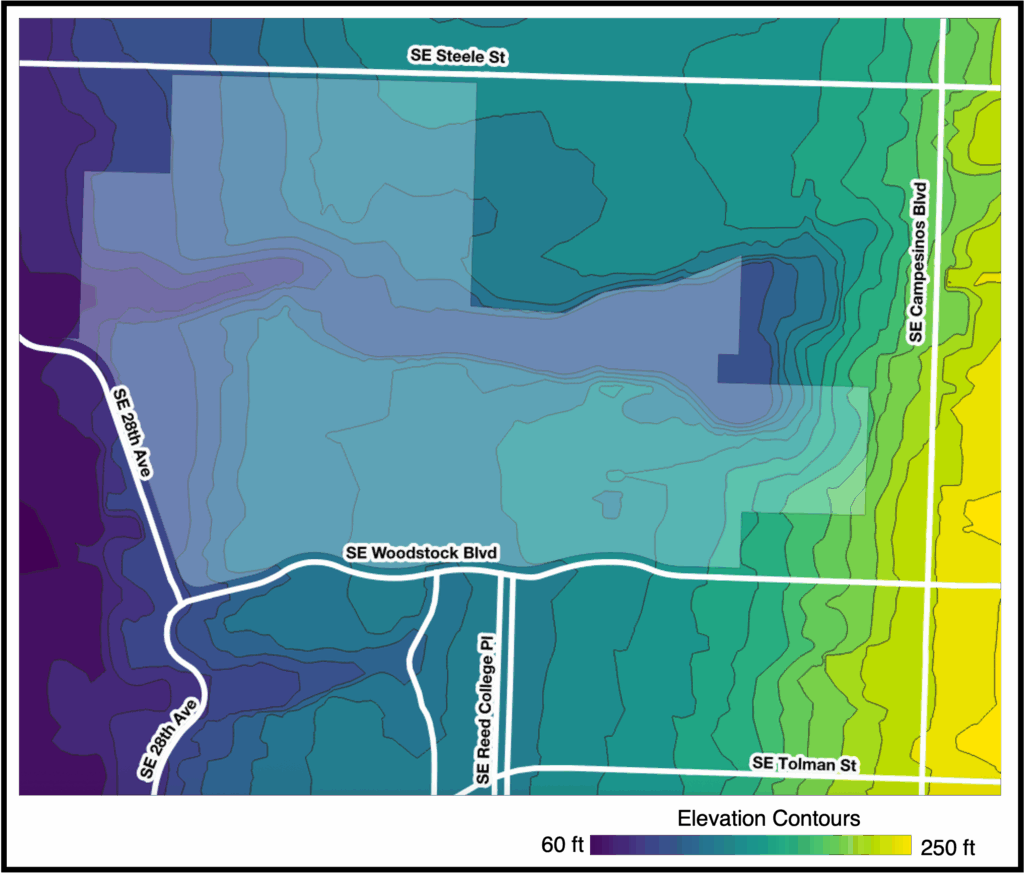
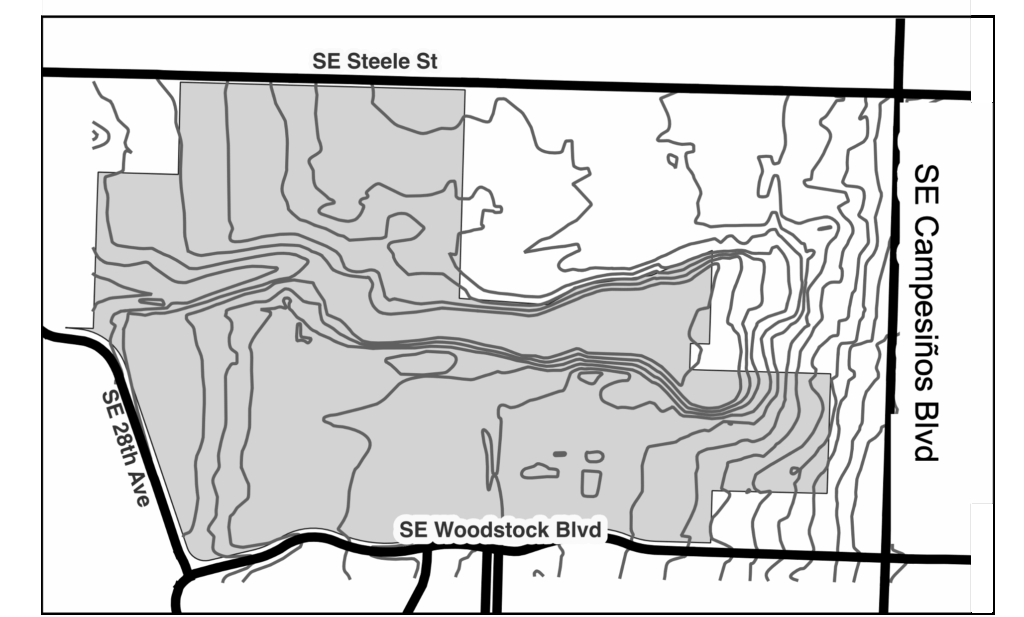
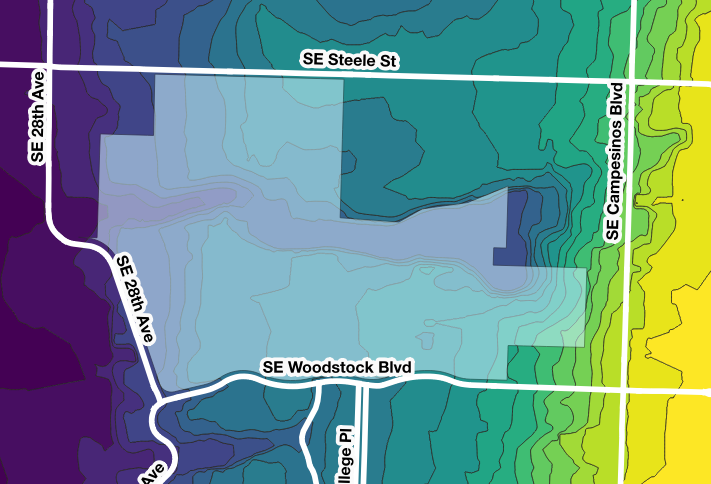
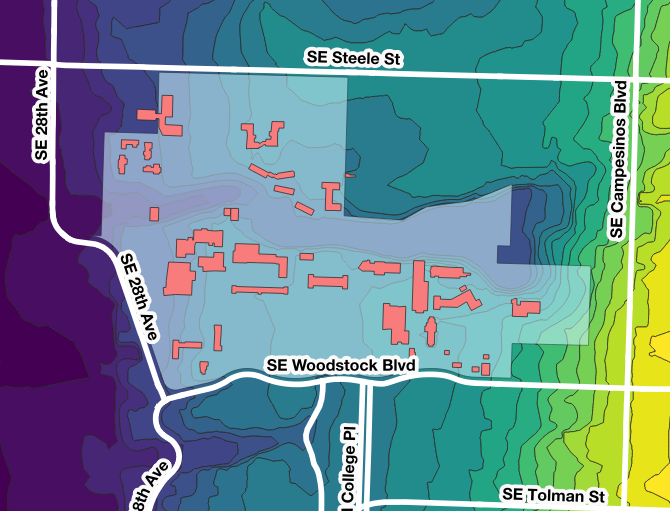
It’s actually surprisingly difficult to convey all the information you’d like to in just black and white and in a small format. I tried grayscale on the map but it didn’t read well, so I just left contour lines, but the colored image shows what’s going on much better.
Chavez Campesinos Blvd
The biggest surprise in making this map was that Chavez has been officially renamed in Oregon’s databases as Campesinos Blvd. They are going to begin changing signs soon. The decision was made official on September 9th by a unanimous city council vote.
How this map was made
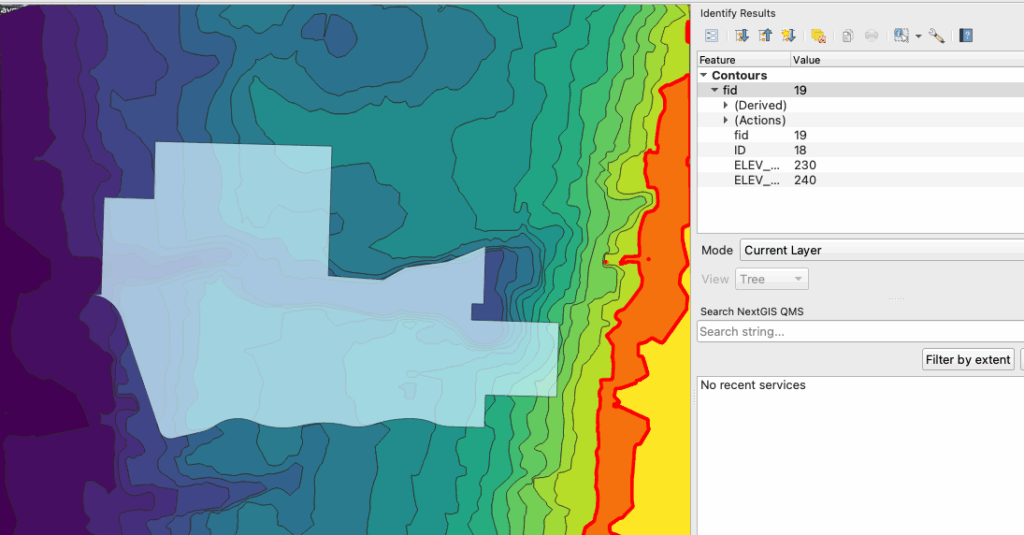
To create the contours on this map, I used a file from Oregon Metro’s Regional Land Information System (RLIS). They host hundreds of publicly available datasets that cover a wide range of topics including geographical maps, but files about Oregon demographics, climate and environmental data, civil buildings, transportation, and more. It’s a great resource for many projects.
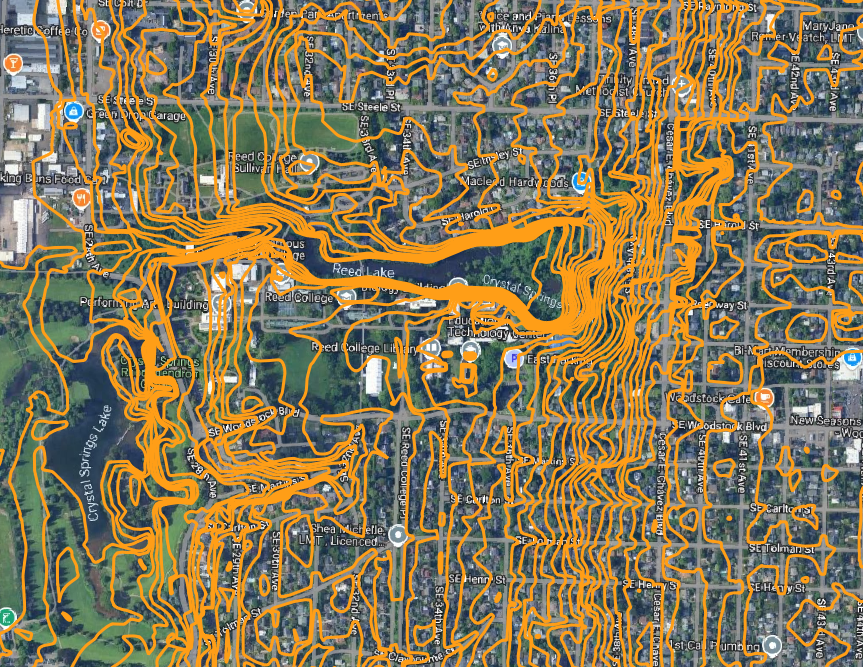
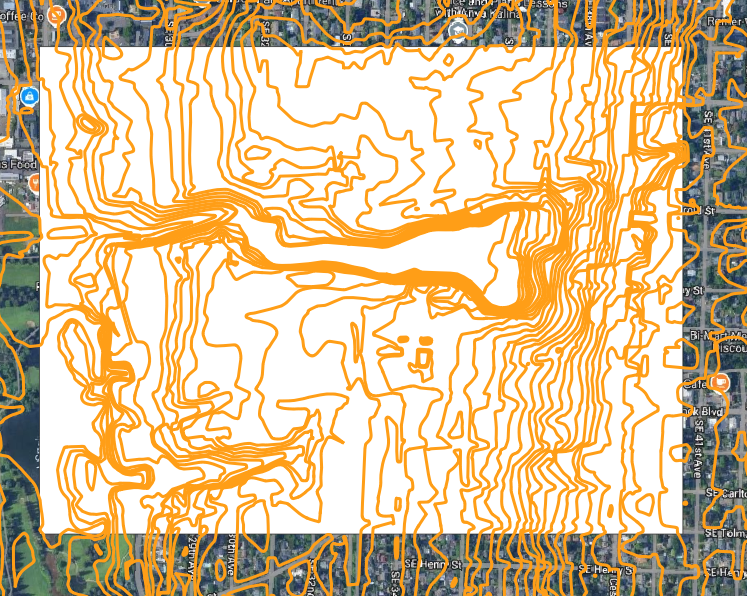
I used the contour map with five feet intervals to get elevations for the Portland area. This came in the form of shape files (.shp), which initially just looks like a series of lines, not shaded areas between lines.
I wanted an area around Reed, not just Reed itself, so I added a rectangular polygon around the area I wanted. I set it to be white and moved it behind the contour lines.
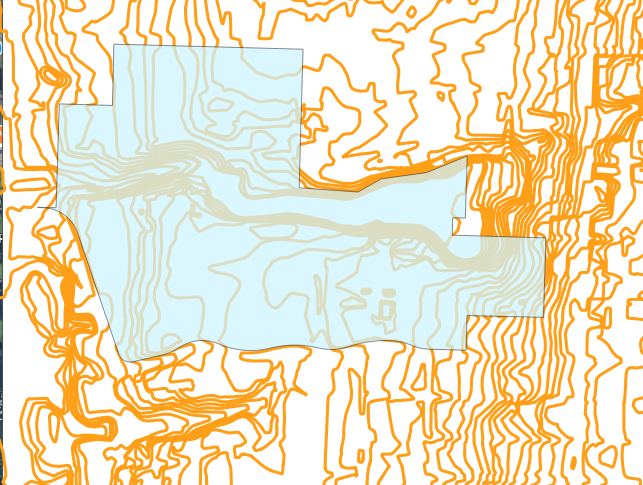
Because I wanted to include Reed College on my map, I also downloaded another shape file that included names and boundaries for different tax lots in Portland. I opened that as a layer in QGIS and filtered the names to just find the boundary of Reed College and remove all other tax lots. Then I overlaid this Reed layer onto the map.
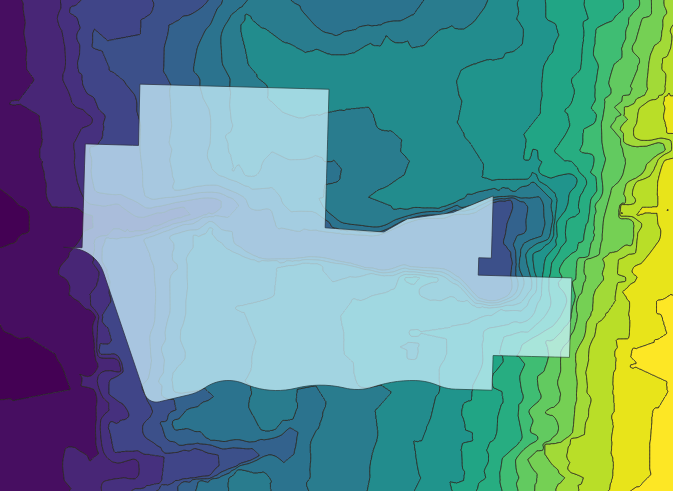
Then I converted the contour lines into polygons so that they could be shaded in by elevation height. There’s a tool in QGIS called “Contour Polygons” that will do this for you. Then I changed the symbology of that layer so that every five feet difference in elevation appeared as a different color along a gradient. I chose five feet because that is the resolution of the original contour file, but I could have chosen a higher number for a less fine-grained graphic.
Lastly, I wanted to add some roads so that it would be easier to orient oneself. QGIS has a Open Streets Map plugin that allows you to add all kinds of things like bike lanes, horse paths, stop lights, and more. From that layer, I selected the streets that I wanted to add to my map. Then I fiddled with the coloring a bit to make things more legible.
To determine that the height of the Woodstock hill is 240 feet, I used the “identify features” tool to see the information for the contour line that overlapped 39th street.
I did the same for an area on the quad. I identified the quad by adding on a layer of Reed buildings, but I thought the map looked too busy with those included, so I removed them for the final graphic. The point of my graphic was to look at the steepness of the Woodstock hill, so the buildings distracted rather than added to the map.
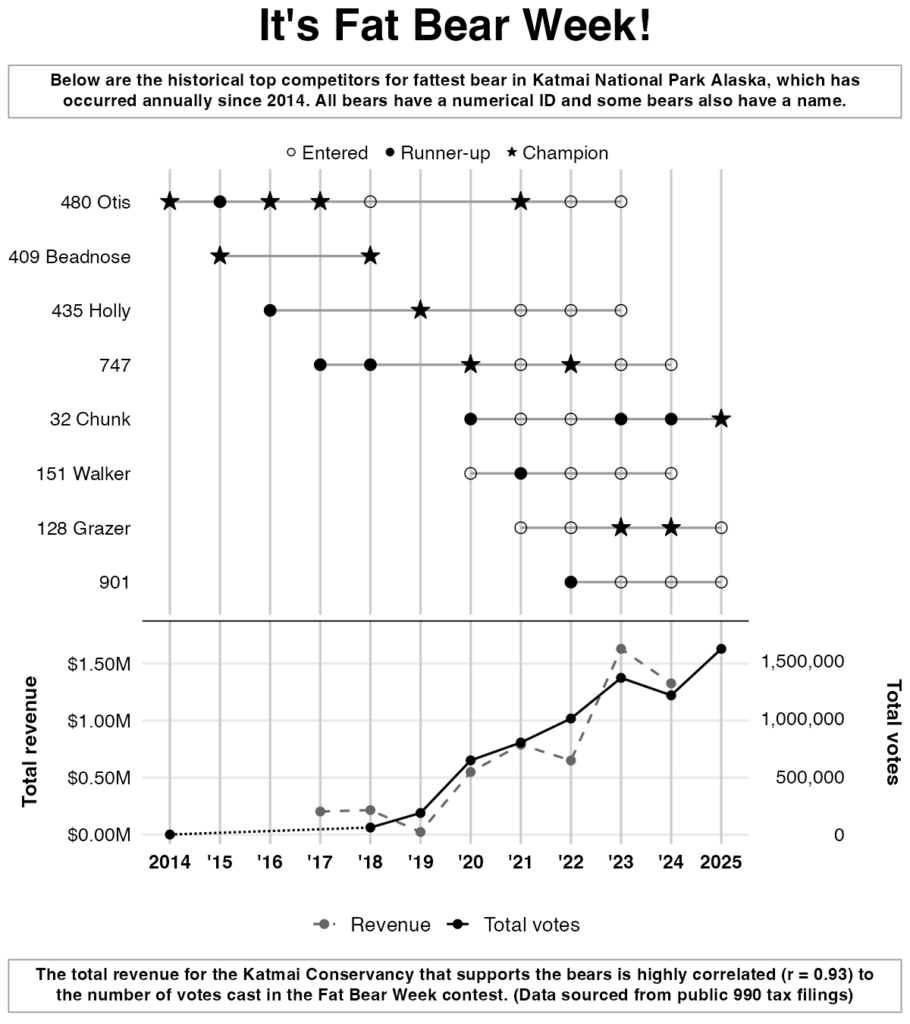
If you haven’t heard, Fat Bear Week is an annual online contest run by Katmai National Park and Preserve in Alaska. The public votes on which brown bear has done the best job of fattening up for winter. The site Explore.org runs live webcams at along the Brooks River where the bears hunt salmon, so people all over the world can watch the bears fish throughout the season.
The contest of bear fatness started in 2014 as a day of single voting, but has expanded into a bracket style tournament that lasts a week. The contest continues until September 29th, so go vote for the fattest bear!
Our graphic this week shows the history of past champions and the correlation between votes in the contest and money raised for the nature preserve.
Where did we find the data?
There’s no official Fat Bear Week repository, so honestly getting the data was kind of a pain. Vote totals and winners were compiled by hand from the National Park Service, Explore.org (which hosts the bear cams and the voting), and news coverage of each year’s contest. The revenue of the Katmai Conservancy was much easier to find and comes from their IRS Form 990 filings. All nonprofits (including schools like Reed) have to file these publicly, which makes them a good source for data. You can find them on ProPublica’s website.
Some information was not possible to find. I couldn’t find the full list of bears entered in the competition for years before 2020, only the champion and runner up were available. The vote counts are also rough estimates that were reported from news sites, not hard numbers from Explore.org. I also couldn’t find any estimates for 2015-2017, but 1700 votes were cast in the first year of the contest.
If you’re interested in looking at the raw data, you can find csv files with data for each year on the Quest repository of the Data@Reed Github page. The ‘summary.csv’ file contains the information used to make the graph, and the other files contain information about individual bears, their relation to one another, and the sources I used to find this data.
Making the Graphic
The code to the graphic is in ‘scripts/analysis.R’ on the Github page, but I will copy the relevant portions of it below. There’s an additional script that pulls together data for the summary file and another that compiles the sources, but these aren’t really material to the analysis.
The final figure is two charts stacked on top of each other and sharing one year axis. I used four packages besides the tidyverse: {ggstar} for star-shaped markers, {patchwork} for stacking plots, {ggtext} for the boxed subtitle and caption, and {scales} for axis labels.
The first bit of the script just to see which bears had the most appearances in the contest so that we could only graph those. When I did this, bear 409 was not included because the data about entries wasn’t great for the first few years. So I forced the appearances to include Beadnose because she was a two-time champion. Then I added some labeling columns so that things would appear nicely on the graph and set how the years would be displayed on the x-axis in order to save room.
Next I started arranging the plot. I created each component of the chart separately and then used the package {patchwork} to arrange them into one figure. I first started with just the title and the boxed text that I wanted to appear at the top and bottom.
Show the graph headings code
title_text <- "It's Fat Bear Week!"
subtitle_text <- "Below are the historical top competitors for fattest bear in Katmai National Park Alaska, which has occurred annually since 2014. All bears have a numerical ID and some bears also have a name."
title_style <- element_text(face = "bold", size = 28, hjust = 0.5)

# Shared boxed-text style for subtitle/caption
boxed_text <- function(outer_margin) {
  element_textbox_simple(
    size = 11, face = "bold", color = "black", hjust = 0.5, halign = 0.5,
    margin = outer_margin, padding = margin(5, 8, 5, 8),
    linetype = 1, box.color = "grey60", linewidth = 0.4, fill = NA
  )
}
</details>
Then I made the top chart by using the geom_segment() command. A start shape isn’t an option within basic ggplot, so that’s where the {ggstar} package came in. Then I just did a lot of adjusting the theme to get things to look exactly how I wanted them. That’s one of the greatest things about R is you can really customize things down to a very fine level.
Show code to make the contest chart
title_text <- "It's Fat Bear Week!"
subtitle_text <- "Below are the historical top competitors for fattest bear in Katmai National Park Alaska, which has occurred annually since 2014. All bears have a numerical ID and some bears also have a name."
title_style <- element_text(face = "bold", size = 28, hjust = 0.5)

# Shared boxed-text style for subtitle/caption
boxed_text <- function(outer_margin) {
  element_textbox_simple(
    size = 11, face = "bold", color = "black", hjust = 0.5, halign = 0.5,
    margin = outer_margin, padding = margin(5, 8, 5, 8),
    linetype = 1, box.color = "grey60", linewidth = 0.4, fill = NA
  )
}
</details>
Next I made the revenue plot with the votes displayed on the same figure as an overlay. To do this, the y-axis on the left was set to show revenue and the y-axis on the right shows total vote. I got lucky here because these numbers scale almost identically. That often doesn’t happen, so then you’d need to use transformations to make your it work on the same figure, or just separate the two data sources to their own figures.
Show code to make the revenue and votes graph
title_text <- "It's Fat Bear Week!"
subtitle_text <- "Below are the historical top competitors for fattest bear in Katmai National Park Alaska, which has occurred annually since 2014. All bears have a numerical ID and some bears also have a name."
title_style <- element_text(face = "bold", size = 28, hjust = 0.5)

# Shared boxed-text style for subtitle/caption
boxed_text <- function(outer_margin) {
  element_textbox_simple(
    size = 11, face = "bold", color = "black", hjust = 0.5, halign = 0.5,
    margin = outer_margin, padding = margin(5, 8, 5, 8),
    linetype = 1, box.color = "grey60", linewidth = 0.4, fill = NA
  )
}
</details>
There’s a little bit of code in there that also runs cor() which calculates the Pearson’s correlation coefficient to test the linear correlation between the two datasets. Note that this isn’t saying anything about the cause of the trends, just that they do go up at a very similar rate, 0.93, where 1 is a perfect relationship.
Then I added code to stack the figures and display only one x-axis at the bottom of the graph.
Adding the text boxes was the fiddliest bit. Honestly, that’s something that probably could have been done easier in an imaging program like PowerPoint or Adobe, but I get stubborn when I know something can be done in R, so I pushed until everything was tweaked just how I wanted it.
Things you could do with this data
Inside the spreadsheets, there’s more data about each bear. There’s information on their family members, their sex, and the year they were born. A more thorough internet search could probably reveal even more than is already in there. Here are a few ideas of other things you could do with this data:
Who’s fatter: mama bears or papa bears?
Does a bear do a better job of fattening up over time or are they the fattest when they’re young and able to exert more energy hunting?
You could trace the lineage of many of the bears to see if champions beget champions or if fatness is maybe more environmental.
You could look up data about salmon numbers in Alaska for the same years as the bear data. Then you could see if there was any correlation between the winners and the salmon abundance. For that, you’d probably need to have a fat score for each bear, which you could subjectively do based off of pictures.
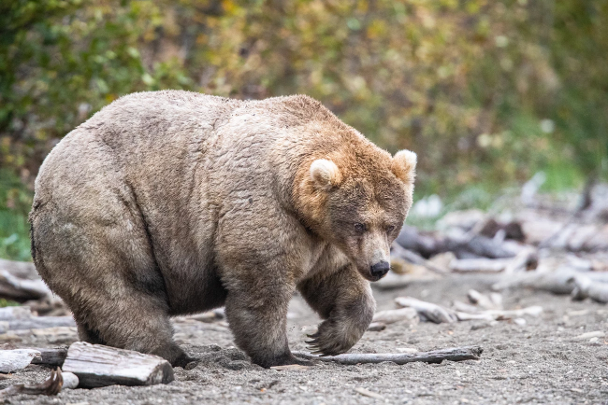
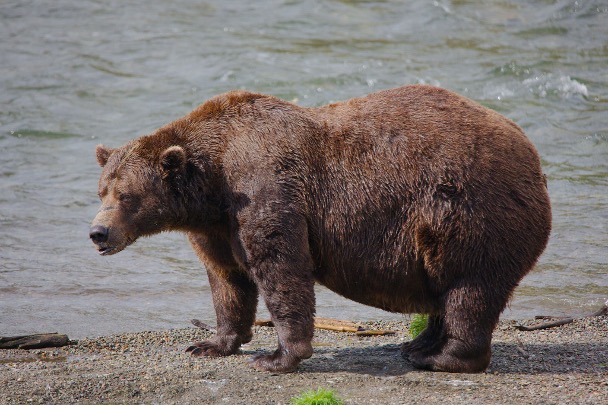
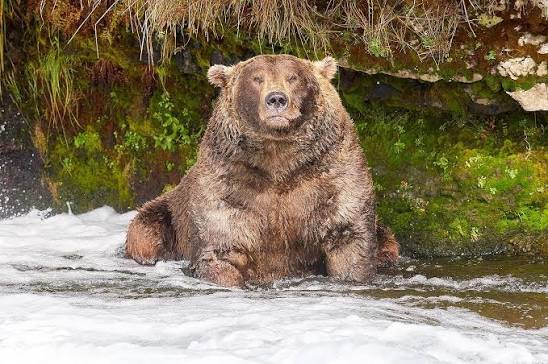
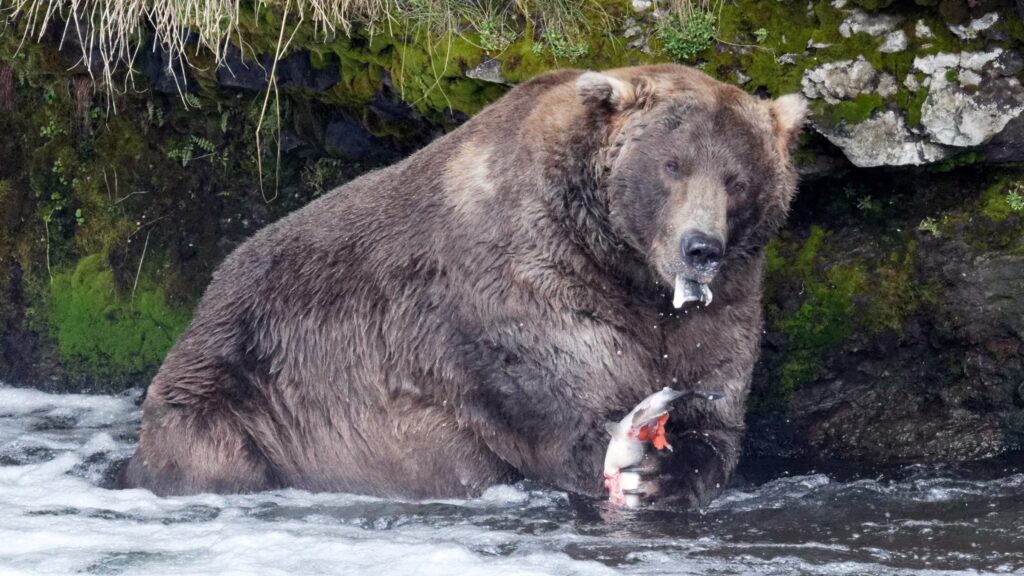
I’ll leave you with a couple pictures of Otis, the four-time champion. RIP, you fat bear!
The most commonly served meal was Fish & Chips at 14 times! It was closely followed by Fried Tofu & Chips at 12 times.
This week we wanted to know what types of meals were being served at commons. We found out that a ton of data on that is available and the chart in the Quest just skims the surface. If you want to learn more about the data, or use it yourself, keep reading for a walk-through or email data@reed.edu.
Where did we find the data?
Every day Bon Appetit’s menu is posted on the Commons homepage. Since we wanted to get access to past menus, the first thing to do was see if that information was cached somewhere. When you go to any Commons’ menu that is not todays, you will see the URL look something like this: https://reed.cafebonappetit.com/cafe/commons-cafe/2026-09-11/ The important thing there is that it ends in the specific date. That means each menu was theoretically stored as its own page that we could access using a web-scraping script.
How did we web scrape the data?
The individual URL dates indicate that each day’s data exists as an inline JS object in the page’s HTML code. So we can write a script to access that and pull out the code. I prefer working in R, so I wrote this script in R. But it could have been written in Python or a number of other languages.
There is actually a lot of data contained in each day’s page. To make the graph simpler (because it has to print in black and white and be legible when small), I decided to only pull dinner menus and only from the SimplyOasis and Classics stations. But more data than this is available if you want to use it!
Here’s the script. The main things it relies on are the packages {httr} and {jsonlite}. {httr} handles the HTTP request — downloading each day’s page — while {jsonlite} takes the JSON-formatted menu data embedded in that page and turns it into something R can actually work with.
Show the script
# load libraries
library(httr)
library(jsonlite)
library(stringr)
library(readr)

####  set selections for scraping
###############################

# get url for menu
cafe_url <- "https://reed.cafebonappetit.com/cafe/commons-cafe/%s/"

# select what meal (can be single value or vector)
daypart <- "Dinner"
# select station (can be single value or vector)
station_wanted <- c("SimplyOASIS", "Classics")
# select date range
dates <- seq(as.Date("2026-01-26"), as.Date("2026-05-14"), by = "day")


####  create functions to:
####  fetch webpage,
####  extract the menu,
####  extract the correct part of day

# downloads one date's menu page as raw HTML
fetch_page <- function(d) {
  url <- sprintf(cafe_url, format(d, "%Y-%m-%d"))
  resp <- GET(url, timeout(30))
  stop_for_status(resp)
  content(resp, as = "text", encoding = "UTF-8")
}

# pulls the menu_items from the JavaScript and parses it as JSON
extract_menu_items <- function(html) {
  pattern <- regex("Bamco\\.menu_items\\s*=\\s*(\\{.*?\\});", dotall = TRUE)
  match <- str_match(html, pattern)
  fromJSON(match[1, 2], simplifyVector = FALSE)
}

# pulls the relevant daypart and returns as a named list
extract_dayparts <- function(html) {
  pattern <- regex(
    "Bamco\\.dayparts\\['(\\d+)'\\]\\s*=\\s*(\\{.*?\\});\\s*\\n\\s*\\}\\)\\(\\);",
    dotall = TRUE
  )
  matches <- str_match_all(html, pattern)[[1]]
  dayparts <- list()
  for (i in seq_len(nrow(matches))) {
    dayparts[[matches[i, 2]]] <- fromJSON(matches[i, 3], simplifyVector = FALSE)
  }
  dayparts
}


####  create function extract the actual meals
###############################

# helper function for pulling menu
# if a is NULL, return b; otherwise return a
# (can't get combinable rows if NULL values are present)
`%||%` <- function(a, b) if (is.null(a)) b else a

# extracts meals based on previous parameters
get_meal_items <- function(d) {
  html <- fetch_page(d)
  menu_items <- extract_menu_items(html)
  dayparts <- extract_dayparts(html)

  # create empty list for output
  rows <- list()
  for (dp in dayparts) {
    # only do this for the correct meal time
    if (!(dp$label %in% daypart)) next

    # find every station that matches the station(s)_wanted
    # using Filter because it's lists not dataframes
    stations <- Filter(\(s) str_trim(str_remove_all(s$label, "<[^>]+>")) %in% station_wanted, dp$stations)

    # make sure there's something there to find
    if (length(stations) == 0) next

    # for every matching station, grab data for each of its items
    for (station in stations) {
      for (item_id in station$items) {
        # get the item's full list of things
        item <- menu_items[[item_id]]
        # make a dataframe out of the following
        rows[[length(rows) + 1]] <- data.frame(
          date = as.character(d),
          meal = dp$label,
          item_name = item$label,
          description = item$description %||% "", # put "" instead of NULL
          price = as.character(item$price %||% ""), # put "" instead of NULL
          dietary_tags = paste(unlist(item$cor_icon), collapse = ", ")
        )
      }
    }
  }
  # bind everything together
  do.call(rbind, rows)
}


####  actually pull the data
###############################

# create empty list for things to go in
rows <- list()
# get meal for each date
for (i in seq_along(dates)) {
  d <- dates[i]
  rows[[i]] <- get_meal_items(d) # this is the line that actually runs everything

  # prints each date just to show progress
  cat(as.character(d), "\n")
  # small pause between requests (technically don't need if it's too slow)
  Sys.sleep(0.1)
}

all_meals <- do.call(rbind, rows)


####  write file
###############################

write_csv(all_meals, "data/dinner_jan26_may14.csv")

</details>
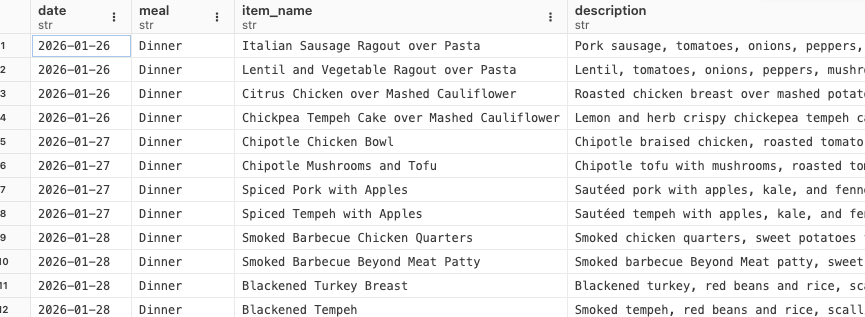
Out of this script, I get a csv file that looks like this:
Wrangling the data and graphing
The way I designed the scraping leaves the data pretty clean, so not a lot needs to be done to work with it. The only thing I need to do is decide what things I want to pull from it. After looking through it, I decided that the best thing would be to look at main ingredients from the item name. I decided to focus on proteins (and mushrooms). Full disclosure, I used Claude to generate this list. I have strong and mixed feelings about AI, but this is one of the uses where it excels and it was much faster than trying to just identify things by most common word because things like “pasta” or “seasoned” came up a lot.
Soy Tempeh: Tempeh (tempeh not described as chickpea or lentil)
Lentil: Lentil
Bean: Bean
I organized the data so that each dish had a column classifying it as the above or “other”. Then the script just counted up the frequency of each. I also classified as “meat”, “veggie”, or “mixed” (because other contained meat and veggie dishes).
Then I made a bar graph with flipped coordinates so the foods would be on the y-axis. When you have a lot of bars to show or things with long names, this is a good thing to do. People can see the difference in bars just as easily, and it makes reading the names simpler. So, consider doing this with your bar graphs.
I colored the bars by meat/veggie/other. I made other striped and to do this I needed to add a bit of more specialized code with the package {ggpattern}. Then I made adjustments to the axis labels, the theme background, and the display of the gridlines.
Show the script
# load library
library(tidyverse)
library(ggpattern)

# load data
raw_menu <- read_csv("data/dinner_jan26_may14.csv")

# most popular single meal
most_popular <- raw_menu |>
  group_by(item_name) |>
  summarize(total = n()) |>
  arrange(desc(total)) |>
  slice(1) |>
  pull(item_name)

# search item_name to tag main ingredient
# group into categories
# order is hierarchical (helps with sausage vs fake sausage, diff kinds of tempeh)
menu <- raw_menu %>%
  mutate(main_ingredient = case_when(
    str_detect(item_name, regex("Beyond|Gardein|Chik|Impossible", ignore_case = TRUE)) ~ "Meat Substitute",
    str_detect(item_name, regex("Chicken|Pollo", ignore_case = TRUE)) ~ "Chicken",
    str_detect(item_name, regex("Beef|Steak|Brisket|Tri-Tip", ignore_case = TRUE)) ~ "Beef",
    str_detect(item_name, regex("Pork|Sausage|Bratwurst", ignore_case = TRUE)) ~ "Pork",
    str_detect(item_name, regex("Turkey", ignore_case = TRUE)) ~ "Turkey",
    str_detect(item_name, regex("Fish|Salmon", ignore_case = TRUE)) ~ "Fish",
    str_detect(item_name, regex("Tofu", ignore_case = TRUE)) ~ "Tofu",
    str_detect(item_name, regex("Mushroom|Portobello", ignore_case = TRUE)) ~ "Mushroom",
    str_detect(item_name, regex("Tempeh", ignore_case = TRUE)) &
      str_detect(item_name, regex("Chickpea|Garbanzo", ignore_case = TRUE)) ~ "Chickpea",
    str_detect(item_name, regex("Tempeh", ignore_case = TRUE)) &
      !str_detect(item_name, regex("Lentil", ignore_case = TRUE))~ "Soy Tempeh",
    str_detect(item_name, regex("Chickpea|Garbanzo", ignore_case = TRUE)) ~ "Chickpea",
    str_detect(item_name, regex("Lentil", ignore_case = TRUE)) ~ "Lentil",
    str_detect(item_name, regex("Bean", ignore_case = TRUE)) ~ "Bean",
    # real dishes with other main ingredient
    item_name %in% c(
      "Garlic Roasted Lamb",
      "Stuffed Peppers with Smashed Potatoes",
      "Eggplant Stew over Polenta",
      "Seared Yams over Polenta",
      "Vegetable Pozole",
      "Pozole Chile Verde"
    ) ~ "Other",
    TRUE ~ NA_character_
  )) %>%
  # drop things like ice cream desserts that aren't dinner
  filter(!is.na(main_ingredient))

# summarize and arrange by count
summary_menu <- menu |>
  group_by(main_ingredient) |>
  summarize(count = n()) |>
  arrange(desc(count))
summary_menu


# add meat vs veggie
# other has lamb, so it's a combo of both
food_type <- c(
  "Chicken" = "Meat",
  "Beef" = "Meat",
  "Pork" = "Meat",
  "Turkey" = "Meat",
  "Fish" = "Meat",
  "Mushroom" = "Veggie",
  "Tofu" = "Veggie",
  "Meat Substitute" = "Veggie",
  "Soy Tempeh" = "Veggie",
  "Chickpea" = "Veggie",
  "Lentil" = "Veggie",
  "Bean" = "Veggie",
  "Other" = "Mixed"
)

summary_menu <- summary_menu |>
  mutate(food = food_type[main_ingredient],
         food_pattern = case_when(food == "Mixed" ~ "Y",
                                  TRUE ~ "N"))

# horizontal bar plot
ingredient_plot <- summary_menu |>
  ggplot(aes(x = reorder(main_ingredient, count), y = count, fill = food, pattern = food_pattern)) +
  geom_col_pattern(
    color = NA,
    pattern_fill = "black",
    pattern_color = NA,
    pattern_density = 0.3,
    pattern_spacing = 0.03,
    pattern_angle = 45
  ) +
  coord_flip() +
  scale_y_continuous(expand = expansion(mult = c(0, 0.05))) +
  scale_fill_manual(
    values = c("Meat" = "gray25", "Veggie" = "gray65", "Mixed" = "gray65"),
    breaks = c("Meat", "Veggie", "Mixed"),
    name = NULL
  ) +
  scale_pattern_manual(values = c("N" = "none", "Y" = "stripe")) +
  guides(
    pattern = "none",
    # this forces only "Both" to look striped
    fill = guide_legend(override.aes = list(pattern = c("none", "none", "stripe")))
  ) +
  labs(
    x = NULL, y = "Number of Times Served",
    title = "What's for Dinner?") +
  theme_minimal(base_size = 16) +
  theme(
    plot.title = element_text(face = "bold", size = 28, hjust = 0.5),
    plot.subtitle = element_text(size = 13, color = "black", margin = margin(b = 10), hjust = 0.5),
    axis.text.x = element_text(color = "black", size = 12),
    axis.text.y = element_text(color = "black", size = 12, margin = margin(r = 0)),
    axis.title.x = element_text(face = "bold", size = 14),
    legend.text = element_text(size = 14),
    legend.position = "top",
    panel.grid.minor.y = element_blank(),
    panel.grid.major.y = element_blank()
  )

ingredient_plot

# save image and a vector copy for print
ggsave("ingredient_plot.png", ingredient_plot, width = 8, height = 6)
ggsave("ingredient_plot.svg", ingredient_plot, width = 8, height = 6)
Things you could do with these scripts
So there’s a lot more to the data than just what I got. I only looked at last semester, but the data goes back to 2014 (I think, you’d have to double check). The JSON data has meals from all times of day and all stations present in commons. It also has prices and dietary tags, like gluten free. Here are a few ideas:
Does the menu change when there are holidays approaching? More pie at Thanksgiving or more halal food during Ramadan?
How many new dishes are added each semester or is the menu consistent over time?
How do the Farm to Fork offerings change with seasons?
Was there any shift after Covid?
If you’re interested in exploring any of these, you can email data@reed.edu or come by the DataLab!
The DataLab is the place to go when you need help on anything data related. Student workers will help you with whatever you bring in, and staff member, Josie Griffin ’09, is also available to meet with. We support any class and everything from personal projects to thesis.
Our website, https://www.reed.edu/data-at-reed/, also has many resources including coding and map making tutorials and guides to help you find, access, and document your data.
Click that link to see our calendar, then drop in any time in green and there’s no limit on the number of hours you can come in.